AI ·
NVIDIA Nemotron 3.5 — new options for local artificial intelligence in business
NVIDIA is expanding the Nemotron family, giving companies new ways to build advanced AI agents. Nemotron 3.5 models can analyse documents, automate work and power intelligent assistants, including on local IT infrastructure.
Source: NVIDIA Blog
NVIDIA is expanding the Nemotron family, giving companies new ways to build advanced AI agents. Nemotron 3.5 models can analyse documents, automate work and power intelligent assistants, including on local IT infrastructure.
A new generation of AI models
NVIDIA Nemotron 3.5 is a family of open models announced in October 2026. NVIDIA describes it as a tool for specialised agents: reasoning, work with documents and images, and task automation.
The official materials highlight three directions:
- Nemotron 3.5 Super VL 120B-A12B — a multimodal model (text, images and video in, text out). It has 120 billion parameters in total and activates 12 billion per token. The model card lists context up to 1 million tokens. BF16 weights are for customisation; NVIDIA documents that precision on 4× H100 or 2× GB200. A separate NVFP4 release is also listed for a single DGX Spark, for text and image, following the vLLM recipe on the model card.
- Nemotron 3.5 Bolt 74B-A9B 24GB — a model compressed from Super VL for everyday agent tasks. It has 74 billion parameters (9 billion active), native quantization of about 2 bits, and is designed to fit in 24 GB of memory. Context on the model card: up to 256 thousand tokens. Inputs include text, images and video.
- Nemotron 3.5 Bolt E4B 4GB — a smaller language model, published on 23 October 2026. NVIDIA post-trained it from Gemma 4 E4B for fast voice and device assistants. It is a text model: about 8 billion parameters, 4 billion of them effective. The 4 GB release is a Q4_K_M quantization for llama.cpp; a separate BF16 release is intended for vLLM.
The model cards mark these releases as ready for commercial and non-commercial use under the OpenMDW-1.1 license. Bolt E4B is also based on Gemma 4, whose base license is Apache 2.0. Before a production deployment, check the current card for the exact release — the family name does not mean every variant has the same requirements.
Local AI infrastructure can stay compact: one server in a rack, or a desk-side system, without moving documents to a public cloud.
Local AI on NVIDIA GB10
DGX Spark is NVIDIA’s compact desk-side system built on the GB10 chip. vLLM’s documentation describes it as a machine for local inference, with a shared 128 GB memory pool for the operating system, model weights and cache.
NVIDIA explicitly positions the Bolt variants for local work on RTX Spark and DGX Spark. Bolt 74B-A9B 24GB is meant to run agent tasks alongside other applications, within about 24 GB. Bolt E4B targets fast conversation on GeForce RTX, Jetson, RTX Spark and DGX Spark. Its model card also lists DGX Spark among tested hardware.
Business applications connect through an API. vLLM documents an OpenAI-compatible server on DGX Spark. Some models are also in NVIDIA’s catalogue at build.nvidia.com — Bolt E4B is published there. Compatibility of a specific release, quantization format and context length has to come from the current recipe. Full-precision BF16 Super VL is not described as a single-GB10 deployment; for that scenario the model card points to the NVFP4 release.
What this means for companies
A local model can support:
- Analysis of internal documents and knowledge bases.
- RAG systems in which the query stays on company infrastructure.
- Task automation with AI agents.
- Intelligent search across organisational material.
- Integration of AI with applications through a local API.
Processing on your own hardware makes it easier to decide where data sits and who can reach it. It does not replace a security policy, access control or a review of the model license.
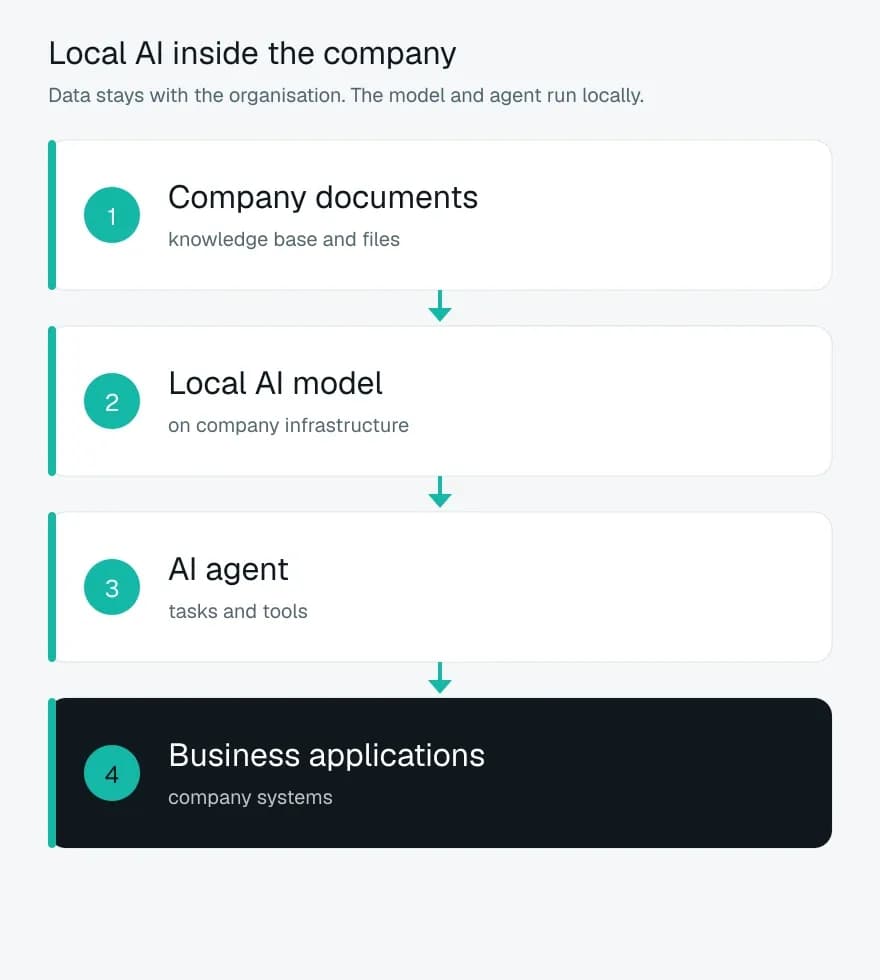
A simple flow: company documents go to a local model, an agent carries out the task, and the result returns to business applications.
Alterkom — infrastructure for local AI
Alterkom builds setups that put artificial intelligence on enterprise infrastructure. With the right hardware, language models and integration software, an organisation can shape an environment from a single server to a broader agent system.
Want to run AI in your own company? Contact Alterkom and see what local AI can do.
Sources
The links below go to the documentation for specific models and to the DGX Spark description. Deployment settings should be read from the current card, not from this summary.
NVIDIA Blog — Nemotron 3.5 Super VL and Bolt (15 October 2026)
NVIDIA Technical Blog — Nemotron 3.5 Super VL
Model card — Nemotron 3.5 Super VL 120B-A12B BF16
Model card — Nemotron 3.5 Super VL 120B-A12B NVFP4 (including DGX Spark)
Model card — Nemotron 3.5 Bolt 74B-A9B 24GB
Technical report — Nemotron 3.5 Bolt 74B-A9B 24GB
Model card — Nemotron 3.5 Bolt E4B 4GB
NVIDIA Research — Nemotron 3.5 Bolt E4B 4GB (23 October 2026)
Planning secure AI agents in your organisation?
Talk to Alterkom about local LLMs, access control and infrastructure for enterprise AI agents.